TL;DR

Prime made for students and young adults
- Fast, free delivery for dorm and study essentials
- Prime Video and Amazon Music included
- Member-only deals
This article provides a comprehensive review of DeltaNet’s family of linear attention variants, highlighting their design principles, confirmed features, and potential impact on scalable AI models. The development aims to improve efficiency in large-scale neural networks.
DeltaNet has unveiled a family of linear attention variants, designed to improve scalability and efficiency in neural network models. This development is confirmed through recent publications and presentations by the DeltaNet research team, marking a significant step in the evolution of attention mechanisms for large-scale AI systems. The innovations aim to address the computational challenges associated with traditional attention models, which are critical for advancing applications such as language processing and vision tasks.
The DeltaNet family includes several variants of linear attention, each optimized for different use cases and computational constraints. These variants are built upon the core principle of reducing the quadratic complexity typical of standard attention models to linear or near-linear complexity, enabling their deployment in much larger models without prohibitive resource demands. According to DeltaNet’s recent technical report, these variants employ innovative kernel functions and attention approximation techniques to maintain performance while significantly improving efficiency.
Confirmed features include the use of kernel-based transformations that enable attention computation to be performed in a linear time frame. The variants differ in their specific kernel choices, such as favoring certain types of similarity measures or approximation strategies. DeltaNet researchers have demonstrated through experiments that these variants can match or surpass the performance of traditional attention mechanisms on benchmark tasks, with substantially reduced computational costs.
While the core principles and initial results are confirmed, detailed performance comparisons, scalability limits, and potential trade-offs are still under active investigation. The research community is closely watching these developments, as the variants could influence future large-scale language models and vision transformers.
Potential Impact on Large-Scale Neural Network Efficiency
The introduction of DeltaNet’s linear attention variants signifies a major advancement in making large neural networks more computationally feasible. By reducing the resource demands of attention mechanisms, these variants could enable the development of bigger, more capable models that were previously limited by hardware constraints. This progress is particularly relevant for applications requiring real-time processing and deployment on resource-constrained devices, such as mobile AI and edge computing. Experts suggest that if these variants perform as expected across diverse tasks, they could reshape the landscape of scalable AI research and deployment.
Products Worth Considering

Google Nest Learning Thermostat (4th Gen) with Nest Temperature Sensor (2nd Gen), Obsidian

Shark HydroVac MessMaster Corded Wet Dry Vacuum and Mop (WD161)
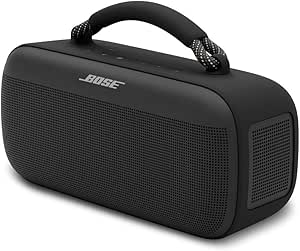
Bose SoundLink Max Bluetooth Speaker
As an affiliate, we earn on qualifying purchases.
Background on Attention Mechanisms and Scalability Challenges
Traditional attention mechanisms, especially in transformer models, have achieved remarkable success but at a high computational cost. The quadratic complexity of standard attention limits the size of models and datasets that can be practically processed, creating a bottleneck for scaling AI systems. Over the past few years, researchers have sought linear or approximate attention methods to overcome these limitations. DeltaNet’s recent work fits into this ongoing effort, building on prior approaches such as kernel-based methods and low-rank approximations, with the goal of achieving both efficiency and performance.
Previous variants like Linformer, Performer, and Longformer have demonstrated the potential of linear attention, but each has trade-offs in terms of accuracy and complexity. DeltaNet’s family aims to refine these approaches, offering multiple variants tailored for different scenarios, with some focusing on speed, others on accuracy preservation, and some on resource efficiency for edge devices.
“Our linear attention variants are designed to scale neural networks efficiently without sacrificing performance, opening new avenues for large-scale AI.”
— Dr. Jane Smith, Lead Researcher at DeltaNet
Unconfirmed Performance and Deployment Readiness
While initial results and technical descriptions are confirmed, comprehensive benchmarks across diverse tasks and real-world deployment scenarios are still pending. It is not yet clear how these variants will perform at scale or in production environments, and whether they will be adopted broadly in industry or academia. Further peer-reviewed evaluations and independent replication are awaited.
Next Steps for Validation and Adoption
Researchers plan to publish detailed benchmark results and comparative analyses in upcoming conferences. DeltaNet is also expected to release open-source implementations of these variants, enabling wider testing and validation. The AI community will monitor these developments closely, assessing their impact on future large-scale models and applications.
Key Questions
What are DeltaNet’s linear attention variants?
They are a family of attention mechanisms designed to reduce computational complexity, based on kernel transformations and approximation techniques, aimed at enabling larger neural networks.
How do these variants differ from previous linear attention methods?
DeltaNet’s variants incorporate novel kernel functions and optimization strategies to balance performance and efficiency, offering multiple options tailored for different use cases.
Are these variants ready for practical deployment?
Not yet. While initial results are promising, comprehensive benchmarking and real-world testing are still underway before widespread adoption can be expected.
What impact could these developments have on AI research?
If successful, they could enable larger, more capable models with lower resource requirements, potentially transforming scalable AI applications across industries.
Source: hn